
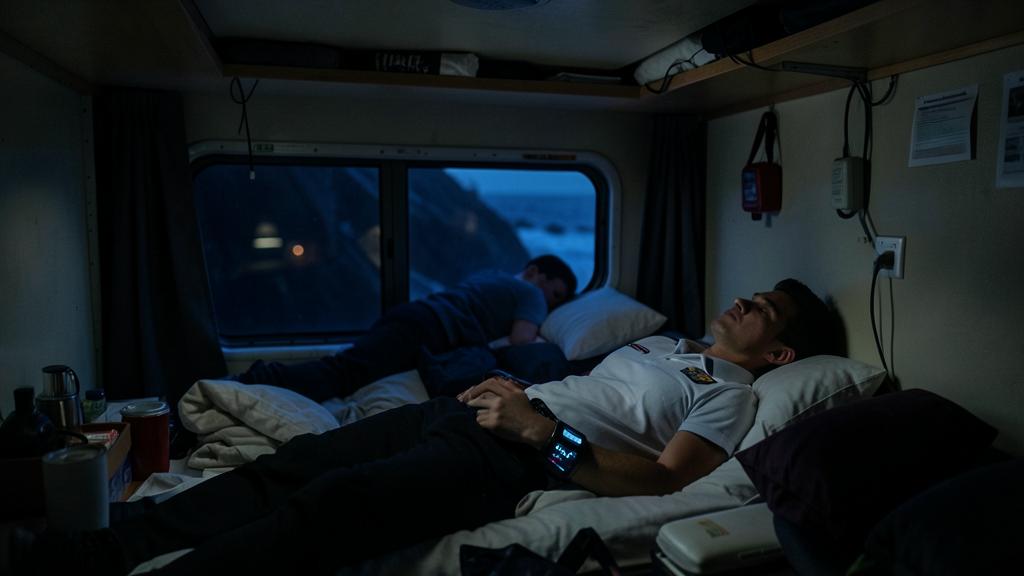
Three instruments are routinely used to put a number on crew fatigue: a wrist device that records movement, a scale on which a person rates their own sleepiness, and a model that predicts alertness from a roster. They are frequently treated as three ways of measuring the same thing, and they are not. Each measures something genuinely different, each is blind in a way the others are not, and most arguments about fatigue data are really arguments in which two people are holding different instruments. Knowing where each one fails is the difference between evidence and decoration.
Three instruments, three different questions
Start by separating the questions, because the instruments answer different ones and none of them answers all three.
How much sleep did this person actually obtain? That is a question about the past, and actigraphy, supported by a sleep diary, is the practical field answer to it. How impaired is this person now? That is a question about the present, and subjective scales are the only instrument fast and cheap enough to ask it routinely, with a performance test as the more rigorous alternative when circumstances allow. How alert would an average crew member be on this pattern? That is a question about a roster that has not been flown yet, and a biomathematical model is the only tool that can answer a question about the future at all.
Confusing the three produces the two most common failures in fatigue work. Using a model to say how tired a specific individual is right now asks a population tool for an individual answer. Using a sleepiness rating to validate a roster asks an instantaneous instrument to describe a pattern. Both look like data, and both are the wrong instrument pointed at the wrong question.
| Instrument | Measures directly | Infers | Cannot see |
|---|---|---|---|
| Actigraphy | Wrist movement over time | Sleep and wake periods, timing, duration | Sleep depth and continuity, quiet wakefulness, whether rest was restorative |
| Subjective scale | A person’s rating of their own sleepiness at an instant | Current impairment | Impairment the person cannot perceive; anything outside the moment of rating |
| Biomathematical model | Nothing — it computes | Average alertness for a sleep and duty history | The individual, sleep quality, workload, life outside the roster |
| Reaction time task | Speed and lapses on a sustained attention task | A component of performance capacity | Judgement, decision making, crew coordination, motivation effects |
Actigraphy measures movement and infers everything else
A wrist actigraph is an accelerometer with a clock. It records movement in short epochs and an algorithm classifies each epoch as sleep or wake. It is the accepted field substitute for laboratory sleep recording because it can be worn for weeks, at home and in a bunk, at a cost that makes a whole crew group feasible.
Its characteristic error follows directly from what it senses. A person lying still and awake produces the same signal as a person asleep, so the algorithm calls it sleep. The practical consequence is systematic: actigraphy tends to overestimate sleep, and it overestimates most in exactly the people and places where the answer matters — someone lying awake in a crew bunk, someone whose sleep is fragmented, someone trying to sleep at the wrong circadian phase. A device that flatters the worst nights is not a neutral instrument.
It is also blind to structure. Two crew members can each show seven hours of recorded sleep, one consolidated and one broken into six fragments by turbulence, cabin noise and a service call, and the recovery obtained is not remotely the same. Actigraphy cannot separate them, because movement does not distinguish sleep stages.
Two operational limitations complete the picture. The record is uninterpretable without a diary: without knowing when the device was removed, when the person was on a long-haul jump seat, or when they lay reading in the dark, the analyst is guessing. And compliance is a real variable — a study with poor wear compliance produces a dataset biased toward the people who were organised enough to wear it, who are not a random sample.
Actigraphy tracks movement to guess sleep, but it can’t tell if someone is just lying still awake. It also can’t measure how restful the sleep was or if it was broken up by disturbances.
A pilot wears an actigraph during a 7-hour rest period in a noisy hotel room. The device records 6.5 hours of “sleep” because the pilot barely moved, but in reality, they only slept 4 hours due to noise disruptions. The actigraph overestimates sleep by 2.5 hours.
Subjective scales measure the moment, and the moment reports late
The Karolinska Sleepiness Scale and the Samn-Perelli fatigue scale are the two instruments most used in flight operations, one rating sleepiness on nine points and the other fatigue on seven. They take seconds, need no equipment, and are the only tools that capture the crew member’s own state at the moment of interest — top of descent, the second sector of a night, the point at which a discretion decision has to be made.
Their central weakness is well established and easy to state: people are unreliable judges of their own impairment when they are sleep-deprived. Under sustained restriction, self-rated sleepiness tends to plateau while measured performance continues to decline. The person is not lying; they have adapted to feeling that way and no longer perceive the gap. Any instrument that depends on perception inherits the limits of perception.
Masking makes it worse in exactly the circumstances aviation cares about. Workload, light, conversation, cold air and caffeine all suppress the feeling of sleepiness without restoring the underlying capacity. A busy approach at four in the morning feels alert and is not, and the rating taken during it will say so.
Then there is the effect of consequence. A scale that is anonymous and used for research produces one distribution of answers. The same scale, filled in where the crew member believes a high score may cost them a sector, a duty or a conversation with a manager, produces another. This is not dishonesty; it is what happens to any self-report attached to an outcome, and it means the reporting environment has to be described before the numbers can be read at all.
The trap. A fall in reported fatigue is not a fall in fatigue. Report rates measure reporting culture at least as strongly as they measure the thing reported, and the fastest way to reduce a fatigue report count is to make reporting inconvenient or consequential. Any downward trend in reports should be treated as a hypothesis about the reporting system until something independent of self-report agrees with it.
Pilots may not realize how tired they are, especially when busy or stimulated. Their self-reports can be misleading, and they might underreport fatigue if they fear consequences.
During a night flight, a pilot rates their sleepiness as “3” on the Karolinska scale during a busy approach, but a performance test later shows reaction times 30% slower than baseline, indicating severe fatigue.
Models describe a population you will never fly with
Biomathematical models predict alertness from a sleep and duty history, generally combining a homeostatic component that accumulates with time awake and dissipates with sleep, and a circadian component that varies with body clock phase. Several are in commercial use in aviation rostering. All of them share the same properties and the same limits, whatever the vendor’s marketing says.
The first limit is that they output an average. A model score describes an expected value across a population of crew members with the same sleep and duty history. Individual differences in vulnerability to sleep loss are large and reasonably stable — the same night of restriction produces very different degradation in different people — and the average hides all of it. A model score does not tell you how the person in the left seat is doing; it tells you how a hypothetical average person would be doing.
The second limit dominates in practice, and it is about inputs. The model’s output is only as good as the sleep it was given, and in rostering use the sleep is almost never measured. It is assumed from the rest period. Feed a model rostered rest and it will faithfully describe the roster, including the fiction that a nine-hour rest period at an outstation produces nine hours of sleep. Commuting, hotel transfers, room noise, time zone, a young child at home and an illness are all invisible to it. Where a model is fed actual sleep, collected by actigraphy or diary, it becomes a far stronger tool — and this is the single upgrade that most changes the quality of a fatigue analysis.
The third limit is regulatory and is often blurred. A model output is not a limit. The applicable limits are the flight and duty time rules — the European Part-ORO flight time limitation scheme, or the United States scheme for passenger operations under its own operating rules, which is structured differently and is not interchangeable — or the provisions of an approved fatigue risk management system. A green score on a model does not make a duty lawful, and a poor score does not by itself make it unlawful. What the model can legitimately do is rank patterns against each other, flag the ones worth examining, and support a case within a management system that has its own approval.
Fatigue models predict average alertness for a group, not how an individual pilot will perform. They assume perfect sleep, which often isn’t true, and can’t account for personal factors like stress or health.
A model predicts a pilot will be “alert” after a 9-hour rest period, but in reality, the pilot only slept 6 hours due to noise and jet lag, leading to actual fatigue not reflected in the model’s output.
The performance test nobody has time to run
The psychomotor vigilance task deserves mention because it is the only common instrument that measures capacity rather than inferring or predicting it. The subject responds to a stimulus that appears at irregular intervals; the outputs of interest are reaction speed and the number of lapses, conventionally counted as responses slower than half a second. It is sensitive to sleep loss and to circadian phase, and it is resistant to learning effects in a way that most cognitive tests are not.
Its limits are equally clear. It measures sustained attention, which is one input to piloting among several — it says nothing directly about decision quality, situational awareness, or how a crew will coordinate. It needs an individual baseline, because absolute scores vary substantially between people who are all perfectly rested. The full version takes ten minutes, which is a long time on a flight deck; abbreviated versions exist and trade sensitivity for practicality. And measuring performance immediately before a duty raises an obvious question the operator must answer in advance: what happens if someone fails.
Matching the instrument to the decision
The practical rule is to name the decision first and then choose the instrument, rather than collecting data and looking for a decision to attach it to.
| Decision | Instrument that fits | Instrument that does not, and why |
|---|---|---|
| Design or compare rosters before they are flown | Model, with sleep assumptions stated explicitly | Subjective scales — there is nobody to ask yet |
| Validate a new pattern in service | Actigraphy plus a scale at fixed points, against a control pattern | Model alone — it will reproduce its own assumptions |
| Judge whether this crew member is fit for this duty now | Self-assessment against the operator’s fitness policy, and the crew member’s own report | Model — it does not know this individual |
| Decide whether to use in-flight rest, and in what order | Scale at a defined point, plus circadian phase of the crew | Actigraphy — the answer arrives days after it is needed |
| Investigate an event after the fact | Reconstructed sleep history, actigraphy if it exists, model as a reconstruction aid | Model alone as proof — it is an estimate of an average, not a finding |
| Establish whether a route or base has a systemic problem | Pooled scales and actigraphy across crews, plus operational data | Individual reports treated as a rate |
The right reflex. Whichever instrument you use, record the sleep actually obtained. Every one of these tools has its largest error in what it assumed about sleep — the actigraph guesses it from stillness, the scale ignores it, the model is handed it. A sleep log alongside the measurement turns three weak instruments into one defensible dataset.
What none of them measures
It is worth being explicit about the gap at the centre of this field. None of these instruments measures operational performance. They measure sleep obtained, perceived sleepiness, predicted average alertness and reaction speed. The quantity everyone actually wants — the margin remaining in this crew, on this approach — is not measured by any of them.
Flight data monitoring is the closest thing an operator has to an outcome measure, and it has its own difficulty: attributing an unstable approach or a late configuration to fatigue rather than to weather, traffic, an unfamiliar airfield or a procedural design problem is rarely defensible from the data alone. Combining flight data events with rostering and sleep data across a large sample can produce a usable signal; a single event plus a model score cannot.
The honest conclusion is that fatigue measurement is a triangulation exercise, not a measurement in the way that fuel or weight is a measurement. Three imperfect instruments that agree are worth considerably more than one instrument that is confident.
Reading the data the operation already has
Most operators already hold more fatigue-relevant data than they use, and a large part of the work is reading it without flattering themselves.
- Crew fatigue reports are a starting point on condition that the denominator is understood: a rate per duty, not a raw count, and interpreted alongside evidence about whether reporting is easy and consequence-free.
- Discretion use — commander’s discretion to extend, and the reduction of rest where the rules allow it — is a valuable indicator precisely because it is recorded for other reasons and is harder to suppress than a voluntary report.
- Roster stability, late changes and standby call-outs bear directly on obtainable sleep and are usually available from the rostering system without any new collection at all.
- And sickness and unfitness call-outs concentrated on particular patterns are worth examining before concluding anything about individuals.
None of these is a fatigue measurement. All of them are cheap, continuous, and capable of pointing at the patterns that deserve the expensive instruments. That is the right relationship between them: routine data selects the target, and actigraphy, scales and models are aimed at it deliberately. Crews and safety staff comparing how their operators do this will find the practical experience under discussion at the FL330 forums.
One last discipline holds all of it together. Write down, before collecting anything, what result would change the roster. A fatigue study with no pre-agreed decision rule tends to end with a report that concludes further study is warranted, and a pattern that continues to be flown exactly as before.


Leave a Reply
You must be logged in to post a comment.